Video coming soon. Start with the reading below.
Now that we know how a client can discover the IP address of a server and create a reliable and secure communication link with it, we want the client to invoke operations offered by the server. To that end, the server uses an adapter — which defines its application programming interface (API) — to translate messages received from the communication link to interface calls implemented by its business logic (see Figure 1.2).
The communication style between a client and a server can be direct or indirect, depending on whether the client communicates directly with the server or indirectly through a broker. Direct communication requires that both processes are up and running for the communication to succeed. However, sometimes this guarantee is either not needed or very hard to achieve, in which case indirect communication is a better fit. An example of indirect communication is messaging. In this model, the sender and the receiver don’t communicate directly, but they exchange messages through a message channel (the broker). The sender sends messages to the channel, and on the other side, the receiver reads messages from it. Later in Messaging (lesson 04.11), we will see how message channels are implemented and how to best use them.
In this lesson, we will focus our attention on a direct communication style called request-response, in which a client sends a request message to the server, and the server replies with a response message. This is similar to a function call but across process boundaries and over the network.
The request and response messages contain data that is serialized in a language-agnostic format. The choice of format determines a message’s serialization and deserialization speed, whether it’s human-readable, and how hard it is to evolve it over time. A textual format like JSON[1] is self-describing and human-readable, at the expense of increased verbosity and parsing overhead. On the other hand, a binary format like Protocol Buffers[2] is leaner and more performant than a textual one at the expense of human read-ability.
When a client sends a request to a server, it can block and wait for the response to arrive, making the communication synchronous. Alternatively, it can ask the outbound adapter to invoke a callback when it receives the response, making the communication asynchronous.
Synchronous communication is inefficient, as it blocks threads that could be used to do something else. Some languages, like JavaScript, C#, and Go, can completely hide callbacks through language primitives such as async/await[3]. These primitives make writing asynchronous code as straightforward as writing synchronous code.
Commonly used IPC technologies for request-response interactions are HTTP and gRPC[4]. Typically, internal APIs used for server-to-server communications within an organization are implemented with a high-performance RPC framework like gRPC. In contrast, external APIs available to the public tend to be based on HTTP, since web browsers can easily make HTTP requests via JavaScript code.
A popular set of design principles for designing elegant and scalable HTTP APIs is representational state transfer (REST[5]), and an API based on these principles is said to be RESTful. For example, these principles include that:
- requests are stateless, and therefore each request contains all the necessary information required to process it;
- responses are implicitly or explicitly labeled as cacheable or non-cacheable. If a response is cacheable, the client can reuse the response for a later, equivalent request.
Given the ubiquity of RESTful HTTP APIs, we will walk through the process of creating an HTTP API in the rest of the chapter.
HTTP
HTTP[6] is a request-response protocol used to encode and transport information between a client and a server. In an HTTP transaction, the client sends a request message to the server’s API endpoint, and the server replies back with a response message, as shown in Figure 5.1.
In HTTP 1.1, a message is a textual block of data that contains a start line, a set of headers, and an optional body:
- In a request message, the start line indicates what the request is for, and in a response message, it indicates whether the request was successful or not.
- The headers are key-value pairs with metadata that describes the message.
- The message body is a container for data.
HTTP is a stateless protocol, which means that everything needed by a server to process a request needs to be specified within the
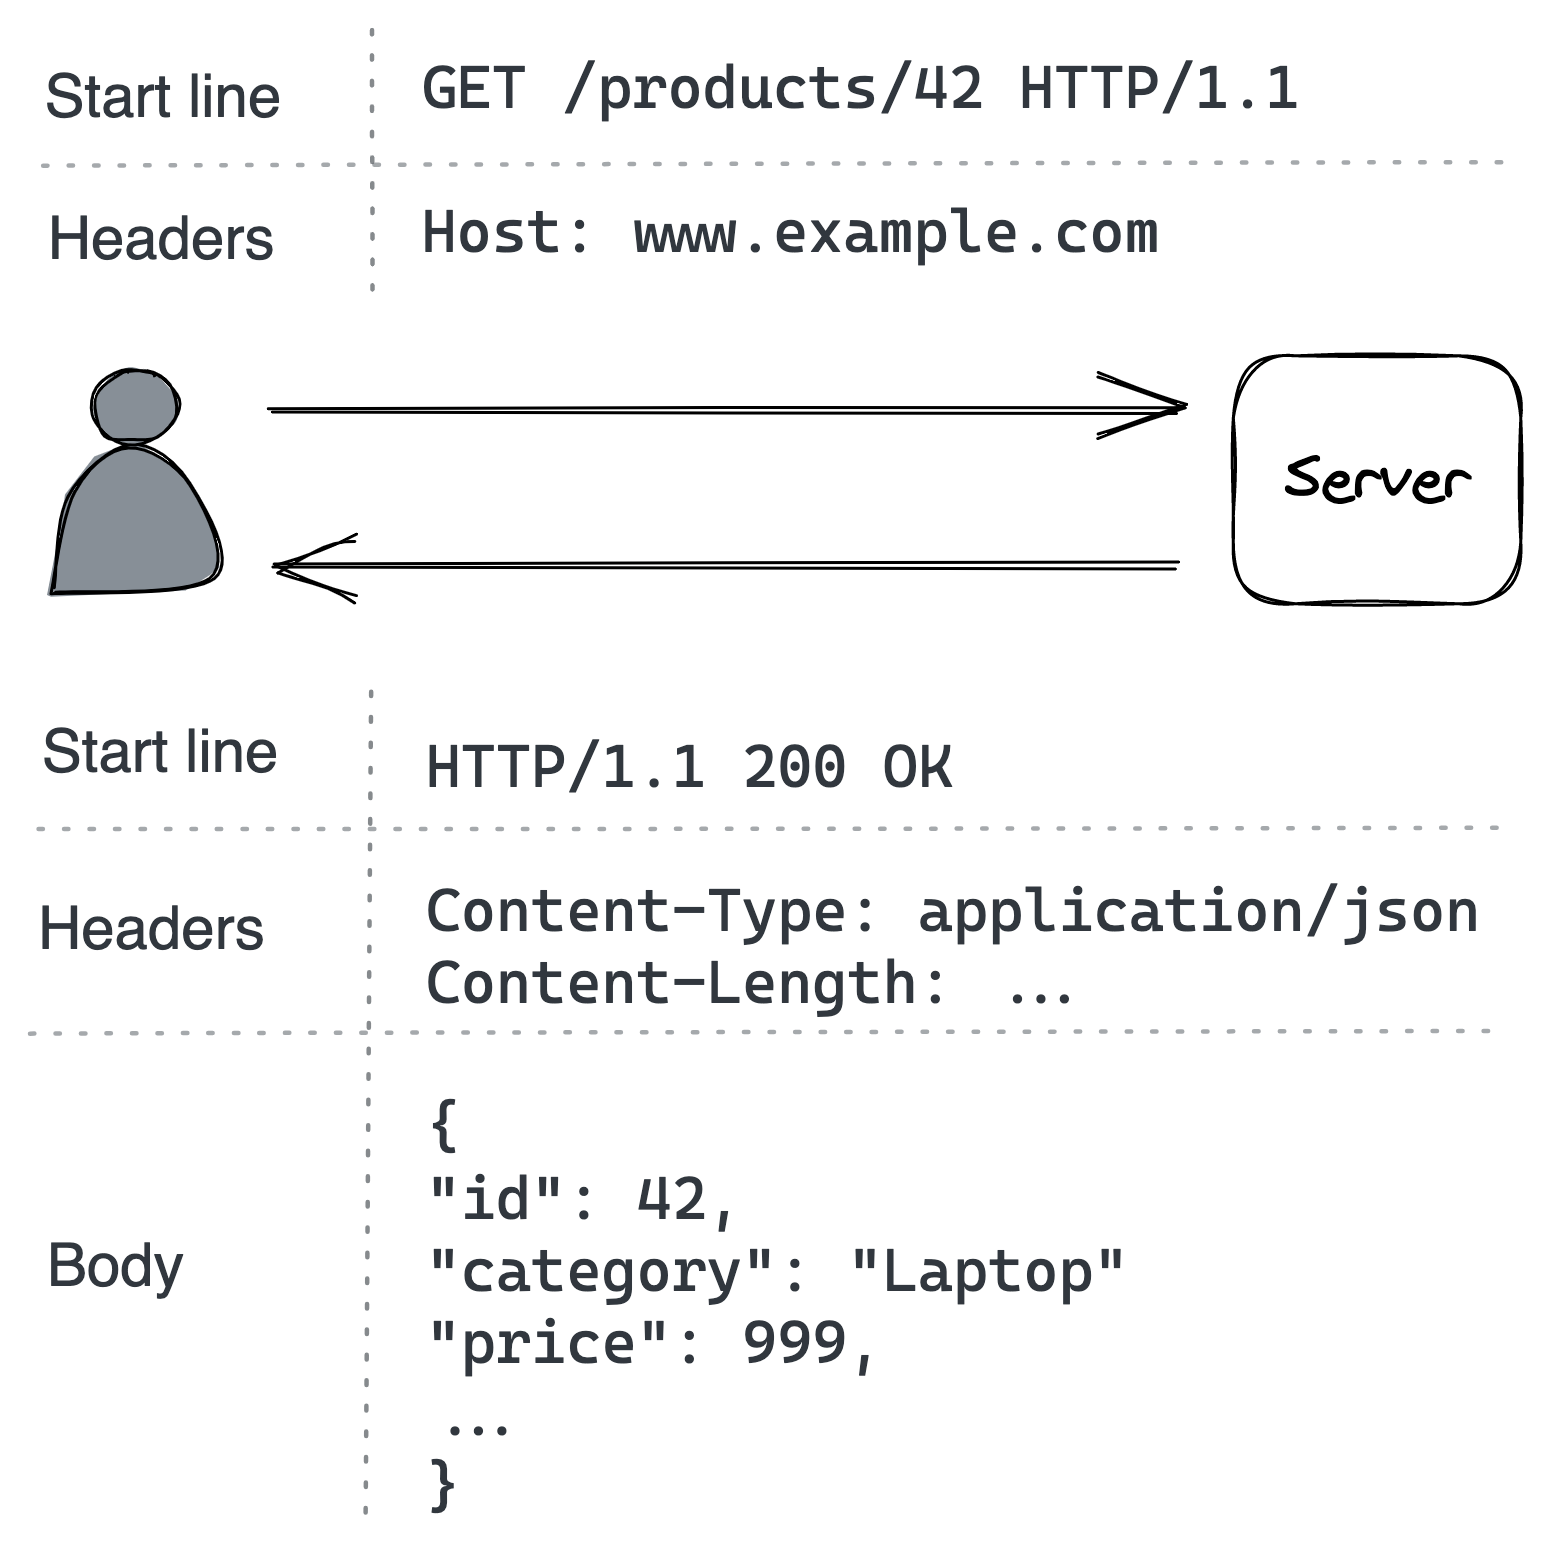
Figure 5.1: An example HTTP transaction between a browser and a web server
request itself, without context from previous requests. HTTP uses TCP for the reliability guarantees discussed in Reliable links (lesson 02.02). When it runs on top of TLS, it’s also referred to as HTTPS.
HTTP 1.1 keeps a connection to a server open by default to avoid needing to create a new one for the next transaction. However, a new request can’t be issued until the response to the previous one has been received (aka head-of-line blocking or HOL blocking); in other words, the transactions have to be serialized. For example, a browser that needs to fetch several images to render an HTML page has to download them one at a time, which can be very inefficient.
Although HTTP 1.1 technically allows some type of requests to be pipelined[7], it still suffers from HOL blocking as a single slow response will block all the responses after it. With HTTP 1.1, the typical way to improve the throughput of outgoing requests is by creating multiple connections. However, this comes with a price because connections consume resources like memory and sockets.
HTTP 2[8] was designed from the ground up to address the main limitations of HTTP 1.1. It uses a binary protocol rather than a textual one, allowing it to multiplex multiple concurrent requestresponse transactions (streams) on the same connection. In early 2020 about half of the most-visited websites on the internet were using the new HTTP 2 standard.
HTTP 3[9] is the latest iteration of the HTTP standard, which is based on UDP and implements its own transport protocol to address some of TCP’s shortcomings[10]. For example, with HTTP 2, a packet loss over the TCP connection blocks all streams (HOL), but with HTTP 3 a packet loss interrupts only one stream, not all of them.
This module uses the HTTP 1.1 standard for illustration purposes since its plain text format is easier to display. Moreover, HTTP 1.1 is still widely used.
Resources
Suppose we would like to implement a service to manage the product catalog of an e-commerce application. The service must allow customers to browse the catalog and administrators to create, update, or delete products. Although that sounds simple, in order to expose this service via HTTP, we first need to understand how to model APIs with HTTP.
An HTTP server hosts resources, where a resource can be a physical or abstract entity, like a document, an image, or a collection of other resources. A URL identifies a resource by describing its location on the server.
In our catalog service, the collection of products is a type of resource, which could be accessed with a URL likehttps://www.example.com/products?sort=price , where:
- https is the protocol;
- www.example.com is the hostname;
- products is the name of the resource;
- ?sort=price is the query string, which contains additional parameters that affect how the service handles the request; in this case, the sort order of the list of products returned in the response.
The URL without the query string is also referred to as the API’s /products endpoint.
URLs can also model relationships between resources. For example, since a product is a resource that belongs to the collection of products, the product with the unique identifier 42 could have the following relative URL: /products/42. And if the product also has a list of reviews associated with it, we could append its resource name to the product’s URL, i.e., /products/42/reviews. However, the API becomes more complex as the nesting of resources increases, so it’s a balancing act.
Naming resources is only one part of the equation; we also have to serialize the resources on the wire when they are transmitted in the body of request and response messages. When a client sends a request to get a resource, it adds specific headers to the message to describe the preferred representation for the resource. The server uses these headers to pick the most appropriate representation[11] for the response. Generally, in HTTP APIs, JSON is used to represent non-binary resources. For example, this is how the representation of /products/42 might look:
{
  "id": 42,
  "category": "Laptop",
  "price": 999
}
Request methods
HTTP requests can create, read, update, and delete (CRUD) resources using request methods. When a client makes a request to a server for a particular resource, it specifies which method to use. You can think of a request method as the verb or action to use on a resource.
The most commonly used methods are POST, GET, PUT, and DELETE. For example, the API of our catalog service could be defined as follows:
- POST /products — Create a new product and return the URL of the new resource.
- GET /products — Retrieve a list of products. The query string can be used to filter, paginate, and sort the collection.
- GET /products/42 — Retrieve product 42.
- PUT /products/42 — Update product 42.
- DELETE /products/42 — Delete product 42.
Request methods can be categorized based on whether they are safe and whether they are idempotent. A safe method should not have any visible side effects and can safely be cached. An idempotent method can be executed multiple times, and the end result should be the same as if it was executed just a single time. Idempotency is a crucial aspect of APIs, and we will talk more about it later in Idempotency in APIs.
| Method | Safe | Idempotent |
|---|---|---|
| POST | No | No |
| GET | Yes | Yes |
| PUT | No | Yes |
| Method | Safe | Idempotent |
|---|---|---|
| DELETE | No | Yes |
Response status codes
After the server has received a request, it needs to process it and send a response back to the client. The HTTP response contains a status code[12] to communicate to the client whether the request succeeded or not. Different status code ranges have different meanings.
Status codes between 200 and 299 are used to communicate success. For example, 200 (OK) means that the request succeeded, and the body of the response contains the requested resource.
Status codes between 300 and 399 are used for redirection. For example, 301 (Moved Permanently) means that the requested resource has been moved to a different URL specified in the response message Location header.
Status codes between 400 and 499 are reserved for client errors. A request that fails with a client error will usually return the same error if it’s retried since the error is caused by an issue with the client, not the server. Because of that, it shouldn’t be retried. Some common client errors are:
- 400 (Bad Request) — Validating the client-side input has failed.
- 401 (Unauthorized) — The client isn’t authenticated.
- 403 (Forbidden) — The client is authenticated, but it’s not allowed to access the resource.
- 404 (Not Found) — The server couldn’t find the requested resource.
Status codes between 500 and 599 are reserved for server errors. A request that fails with a server error can be retried as the issue that caused it to fail might be temporary. These are some typical server status codes:
- 500 (Internal Server Error) — The server encountered an unexpected error that prevented it from handling the request.
- 502 (Bad Gateway) — The server, while acting as a gateway or proxy, received an invalid response from a downstream server it accessed while attempting to handle the request.[13]
- 503 (Service Unavailable) — The server is currently unable to handle the request due to a temporary overload or scheduled maintenance.
OpenAPI
Now that we understand how to model an API with HTTP, we can write an adapter that handles HTTP requests by calling the business logic of the catalog service. For example, suppose the service is defined by the following interface:
interface CatalogService
{
  List<Product> GetProducts(...);
  Product GetProduct(...);
  void AddProduct(...);
  void DeleteProduct(...);
  void UpdateProduct(...)
}
So when the HTTP adapter receives a GET /products request to retrieve the list of all products, it will invoke the GetProducts(...) method and convert the result into an HTTP response. Although this is a simple example, you can see how the adapter connects the IPC mechanism (HTTP) to the business logic.
We can generate a skeleton of the HTTP adapter by defining the
API of the service with an interface definition language (IDL). An IDL is a language-independent definition of the API that can be used to generate boilerplate code for the server-side adapter and client-side software development kits (SDKs) in your languages of choice.
The OpenAPI[14] specification, which evolved from the Swagger project, is one of the most popular IDLs for RESTful HTTP APIs. With it, we can formally describe the API in a YAML document, including the available endpoints, supported request methods, and response status codes for each endpoint, and the schema of the resources’ JSON representation.
For example, this is how part of the /products endpoint of the catalog service’s API could be defined:
openapi: 3.0.0
info:
  version: "1.0.0"
  title: Catalog Service API
paths:
  /products:
    get:
      summary: List products
      parameters:
        - in: query
          name: sort
          required: false
          schema:
            type: string
      responses:
        "200":
          description: list of products in catalog
          content:
            application/json:
              schema:
type: array
items:
$ref: "#/components/schemas/ProductItem"
"400":
description: bad input
components:
schemas:
ProductItem:
type: object
required:
- id
- name
- category
properties:
id:
type: number
name:
type: string
category:
type: stringAlthough this is a very simple example and we won’t go deeper into OpenAPI, it should give you an idea of its expressiveness. With this definition, we can then run a tool to generate the API’s documentation, boilerplate adapters, and client SDKs.
Evolution
An API starts out as a well-designed interface[15]. Slowly but surely, it will have to change to adapt to new use cases. The last thing we want to do when evolving an API is to introduce a breaking change that requires all clients to be modified at once, some of which we might have no control over.
There are two types of changes that can break compatibility, one at the endpoint level and another at the message level. For example, if we were to change the /products endpoint to /new-products, it would obviously break clients that haven’t been updated to support the new endpoint. The same applies when making a previously optional query parameter mandatory.
Changing the schema of request or response messages in a backward-incompatible way can also wreak havoc. For example, changing the type of the category property in the Product schema from string to number is a breaking change that would cause the old deserialization logic to blow up in clients. Similar arguments[16] can be made for messages represented with other serialization formats, like Protocol Buffers.
REST APIs should be versioned to support breaking changes, e.g., by prefixing a version number in the URLs (/v1/products/). However, as a general rule of thumb, APIs should evolve in a backward-compatible way unless there is a very good reason. Although backward-compatible APIs tend not to be particularly elegant, they are practical.
Idempotency
When an API request times out, the client has no idea whether the server actually received the request or not. For example, the server could have processed the request and crashed right before sending a response back to the client.
An effective way for clients to deal with transient failures such as these is to retry the request one or more times until they get a response back. Some HTTP request methods (e.g., PUT, DELETE) are considered inherently idempotent as the effect of executing multiple identical requests is identical to executing only one request[17]. For example, if the server processes the same PUT request for the same resource twice in a row, the end effect would be the same as if the PUT request was executed only once.
But what about requests that are not inherently idempotent? For example, suppose a client issues a POST request to add a new product to the catalog service. If the request times out, the client has no way of knowing whether the request succeeded or not. If the request succeeds, retrying it will create two identical products, which is not what the client intended.
In order to deal with this case, the client might have to implement some kind of reconciliation logic that checks for duplicate products and removes them when the request is retried. You can see how this introduces a lot of complexity for the client. Instead of pushing this complexity to the client, a better solution would be for the server to create the product only once by making the POST request idempotent, so that no matter how many times that specific request is retried, it will appear as if it only executed once.
For the server to detect that a request is a duplicate, it needs to be decorated with an idempotency key — a unique identifier (e.g., a UUID). The identifier could be part of a header, like Idempotency- Key in Stripe’s API[18]. For the server to detect duplicates, it needs to remember all the request identifiers it has seen by storing them in a database. When a request comes in, the server checks the database to see if the request ID is already present. If it’s not there, it adds the request identifier to the database and executes the request. Request identifiers don’t have to be stored indefinitely, and they can be purged after some time.
Now here comes the tricky part. Suppose the server adds the request identifier to the database and crashes before executing the request. In that case, any future retry won’t have any effect because the server will think it has already executed it. So what we really want is for the request to be handled atomically: either the server processes the request successfully and adds the request identifier to the database, or it fails to process it without storing the request identifier.
If the request identifiers and the resources managed by the server are stored in the same database, we can guarantee atomicity with ACID transactions[19]. In other words, we can wrap the product creation and request identifier log within the same database transaction in the POST handler. However, if the handler needs to make external calls to other services to handle the request, the implementation becomes a lot more challenging[20], since it requires some form of coordination. Later, in Sagas in Asynchronous transactions, we will learn how to do just that.
Now, assuming the server can detect a duplicate request, how should it be handled? In our example, the server could respond to the client with a status code that signals that the product already exists. But then the client would have to deal with this case differently than if it had received a successful response for the first POST request (201 Created). So ideally, the server should return the same response that it would have returned for the very first request.
So far, we have only considered a single client. Now, imagine the following scenario:
- Client A sends a request to create a new product. Although the request succeeds, the client doesn’t receive a timely response.
- Client B deletes the newly created product.
- Client A retries the original creation request.
How should the server deal with the request in step 3? From client’s A perspective, it would be less surprising[21] to receive the original creation response than some strange error mentioning that the resource created with that specific request identifier has been deleted. When in doubt, it’s helpful to follow the principle of least astonishment.
To summarize, an idempotent API makes it a lot easier to implement clients that are robust to failures, since they can assume that requests can be retried on failure without worrying about all the possible edge cases.
Communicating over networks is what makes a system distributed. It’s all too easy to ignore the “leaking” complexity that goes into it, since modern programming languages and frameworks make it look like invoking a remote API is no different from calling a local function. I know I did at first and eventually learned this lesson after spending days investigating weird degradations that ultimately turned out to be caused by exhausted socket pools or routers dropping packets.
Since then, I spend a great deal of time thinking of everything that can go wrong when a remote request is made: socket pools can be exhausted, TLS certificates can expire, DNS servers can become unavailable, routers can become congested and drop packets, non-idempotent requests can result in unexpected states, and the list goes on. The only universal truth is that the fastest, safest, most secure, and reliable network call is the one you don’t have to make. And I hope that by reading about TCP, TLS, UDP, DNS, and HTTP, you also have (re)discovered a profound respect for the challenges of building networked applications.
References
- “ECMA-404: The JSON data interchange syntax,” https://www.ecma-international.org/publications-and-standards/standards/ecma-404/
- “Protocol Buffers: a language-neutral, platform-neutral extensible mechanism for serializing structured data,” https://developers.google.com/protocol-buffers
- “Asynchronous programming with async and await,” https://docs.microsoft.com/en-us/dotnet/csharp/programming-guide/concepts/async/
- “gRPC: A high performance, open source universal RPC framework,” https://grpc.io/
- “Representational State Transfer,” https://www.ics.uci.edu/~fielding/pubs/dissertation/rest_arch_style.htm
- “Hypertext Transfer Protocol,” https://en.wikipedia.org/wiki/Hypertext_Transfer_Protocol
- “HTTP pipelining,” https://en.wikipedia.org/wiki/HTTP_pipelining
- “RFC 7540: Hypertext Transfer Protocol Version 2 (HTTP/2),” https://tools.ietf.org/html/rfc7540
- “HTTP/3 is next Generation HTTP. Is it QUIC enough?,” https://www.youtube.com/watch?v=rlN4F1oyaRM
- “Comparing HTTP/3 vs. HTTP/2 Performance,” https://blog.cloudflare.com/http-3-vs-http-2/
- “HTTP Content negotiation,” https://developer.mozilla.org/en-US/docs/Web/HTTP/Content_negotiation
- “HTTP Status Codes,” https://httpstatuses.com/
- In this module, we will sometimes classify service dependencies as upstream or downstream depending on the direction of the dependency relationship. For example, if service A makes requests to service B, then service B is a downstream dependency of A, and A is an upstream dependency of B. Since there is no consensus in the industry for these terms, other texts might use a different convention.
- “OpenAPI Specification,” https://swagger.io/specification/
- Or at least it should.
- “Schema evolution in Avro, Protocol Buffers and Thrift,” https://martin.kleppmann.com/2012/12/05/schema-evolution-in-avro-protocol-buffers-thrift.html
- “Idempotent Methods,” https://datatracker.ietf.org/doc/html/rfc7231#section-4.2.2
- “Designing robust and predictable APIs with idempotency,” https://stripe.com/blog/idempotency
- “Using Atomic Transactions to Power an Idempotent API,” https://brandur.org/http-transactions
- “Implementing Stripe-like Idempotency Keys in Postgres,” https://brandur.org/idempotency-keys
- “Making retries safe with idempotent APIs,” https://aws.amazon.com/builders-library/making-retries-safe-with-idempotent-APIs/