Video coming soon. Start with the reading below.
Several things can go wrong when a client sends a request to a server. In the best case, the client sends a request and receives a response. But what if no response comes back after some time? In that case, it’s impossible to tell whether the server is just very slow, it crashed, or a message couldn’t be delivered because of a network issue (see Figure 7.1).
In the worst case, the client will wait forever for a response that will never arrive. The best it can do is make an educated guess, after some time has passed, on whether the server is unavailable. The client can configure a timeout to trigger if it hasn’t received a response from the server after a certain amount of time. If and when the timeout triggers, the client considers the server unavailable and either throws an error or retries the request.
The tricky part is deciding how long to wait for the timeout to trigger. If the delay is too short, the client might wrongly assume the server is unavailable; if the delay is too long, the client might waste time waiting for a response that will never arrive. In summary, it’s not possible to build a perfect failure detector.
But a process doesn’t need to wait to send a message to find out that the destination is not reachable. It can also proactively try to maintain a list of available processes using pings or heartbeats.
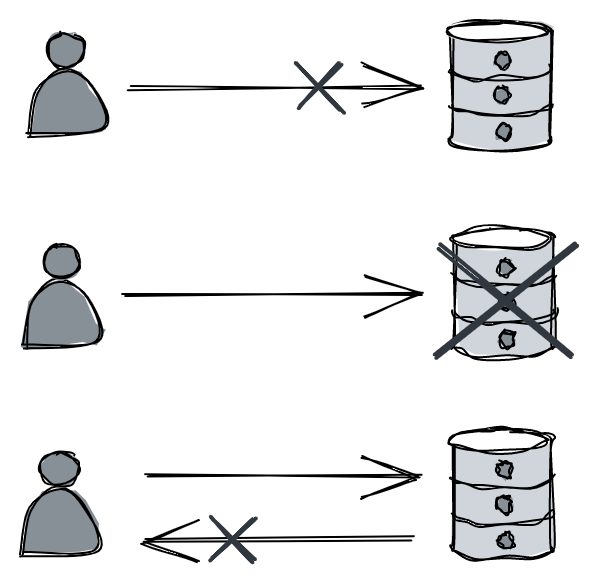
Figure 7.1: The client can’t tell whether the server is slow, it crashed or a message was delayed/dropped because of a network issue.
A ping is a periodic request that a process sends to another to check whether it’s still available. The process expects a response to the ping within a specific time frame. If no response is received, a time-out triggers and the destination is considered unavailable. However, the process will continue to send pings to it to detect if and when it comes back online.
A heartbeat is a message that a process periodically sends to another. If the destination doesn’t receive a heartbeat within a specific time frame, it triggers a timeout and considers the process unavailable. But if the process comes back to life later and starts sending out heartbeats, it will eventually be considered to be available again.
Pings and heartbeats are generally used for processes that interact with each other frequently, in situations where an action needs to be taken as soon as one of them is no longer reachable. In other circumstances, detecting failures just at communication time is good enough.